Przemysław TarkowskiSoftware engineer · AI agent toolingEngineer · AI agent tooling

I build the harness my AI agents run on, and the tools I work with them in.

Since late 2025 I've run Claude Code agents every day and built the software around them: an operating layer, a session launcher and an operations console. Personal tools, not products for clients. By day I'm a software engineer in Warsaw with 11+ years of shipping mobile games in C# and Unity.

  • LLM agents
  • Claude Code
  • Agent harnesses
  • Human-in-the-loop
  • Evals · blind A/B
  • C# · Unity
  • AWS (2019 to 2022)
  • LangGraph (learning)
11+ yrs
shipping mobile gamesC# · Unity, since 2015
100M+
lifetime downloads, Crazy Kicksole engineer since 2024
852
agent sessions since Feb 202632,000+ commits in the agent repo
6 of 8
rules that helped in a blind A/Bsame split on two models
SYS/01 · Selected work

What I've built around my agents

Personal tools I build and run every day, plus one learning build. The code is written by AI agents under my specification, test contracts and review of the result.

Behavior · Flagship Daily use

TarkOS

An operating layer that makes a Claude Code agent run on files, not prompts.

Side project · v0.1 · open-source release in preparation

Problem

Coding agents start every session from zero: re-taught by prompt, unsure which calls are theirs to make, and quick to say "done" without proof.

Instructions, hooks, a decision tray and a capture pipeline for Claude Code. Reversible work is done and logged for a one-command revert; irreversible calls wait for me. Every correction I make becomes a written rule, and I test rules in blind A/B runs to see which ones actually help.

  • Claude Code
  • Agent harness
  • Hooks
  • Evals · blind A/B
852 agent sessions · 32,000+ commits since Feb 2026 Case study : TarkOS
fig.1 · session.replay ~/launcher · overnight run
Step 18/18Elapsed 1:36:55Model claude
result 7/14 → 10/14 · a flaky run recorded, not hiddenRecorded from a real TarkOS session (overnight run, 2026-09-23). Paths shortened, private details removed, timings real.
Interface Daily use

Launcher

A desktop launcher for Claude Code, with several live sessions side by side.

In daily use · written by AI agents under my specification, test contracts and review · private repo

Problem

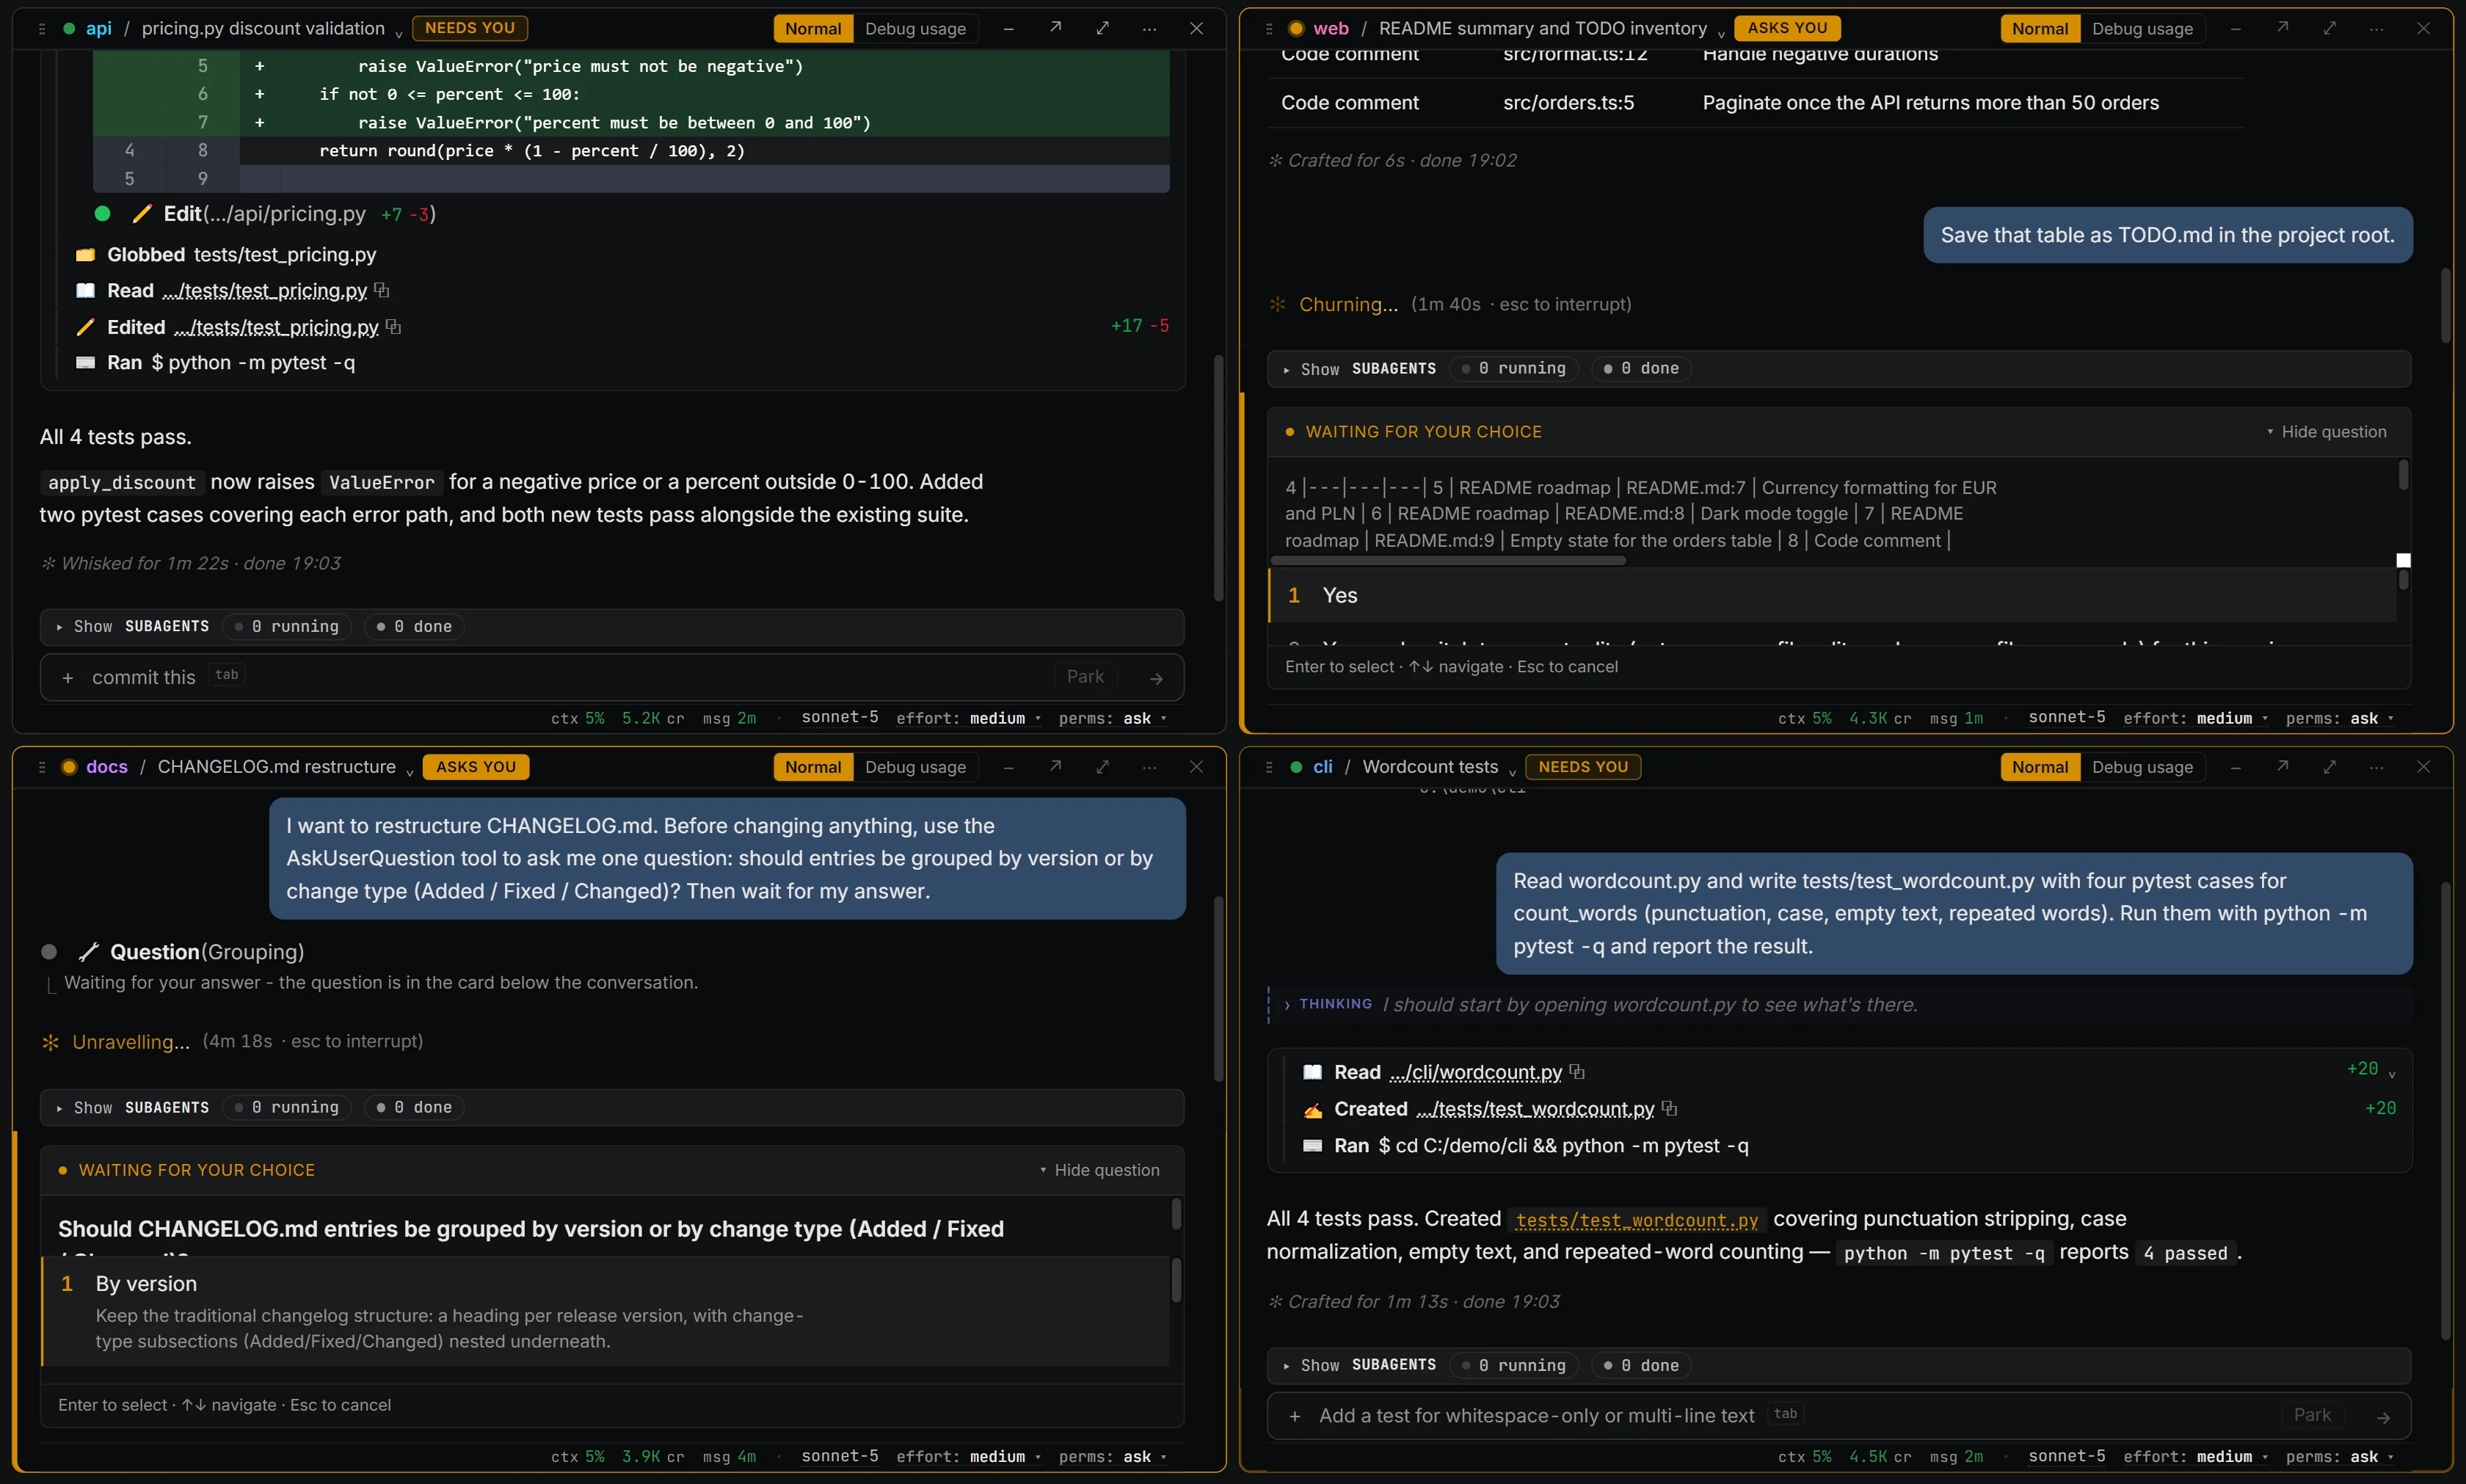
Running four agents in four terminal tabs means missing the one that's waiting for you, and reading tool output as raw text.

Each pane hosts a real claude process and renders its stream as messages, diffs and tool widgets, with the terminal one click away. A measured fix took frame-time p95 at four panes from 765 ms to 31 ms.

  • Tauri 2
  • Rust
  • xterm.js
3,400+ tests · 1,350+ commits since April 2026 Details : Launcher
fig.2 · launcher · 4 live sessions real capture · demo folders
FIG. 2 · Real capture, throwaway demo folders. Two sessions are waiting for me.
Control

TarkOS Cockpit

The operations console for my agents: what ran, what needs me, what to decide.

Formerly Mission Control · written by AI agents under my specification, test contracts and review · private

Problem

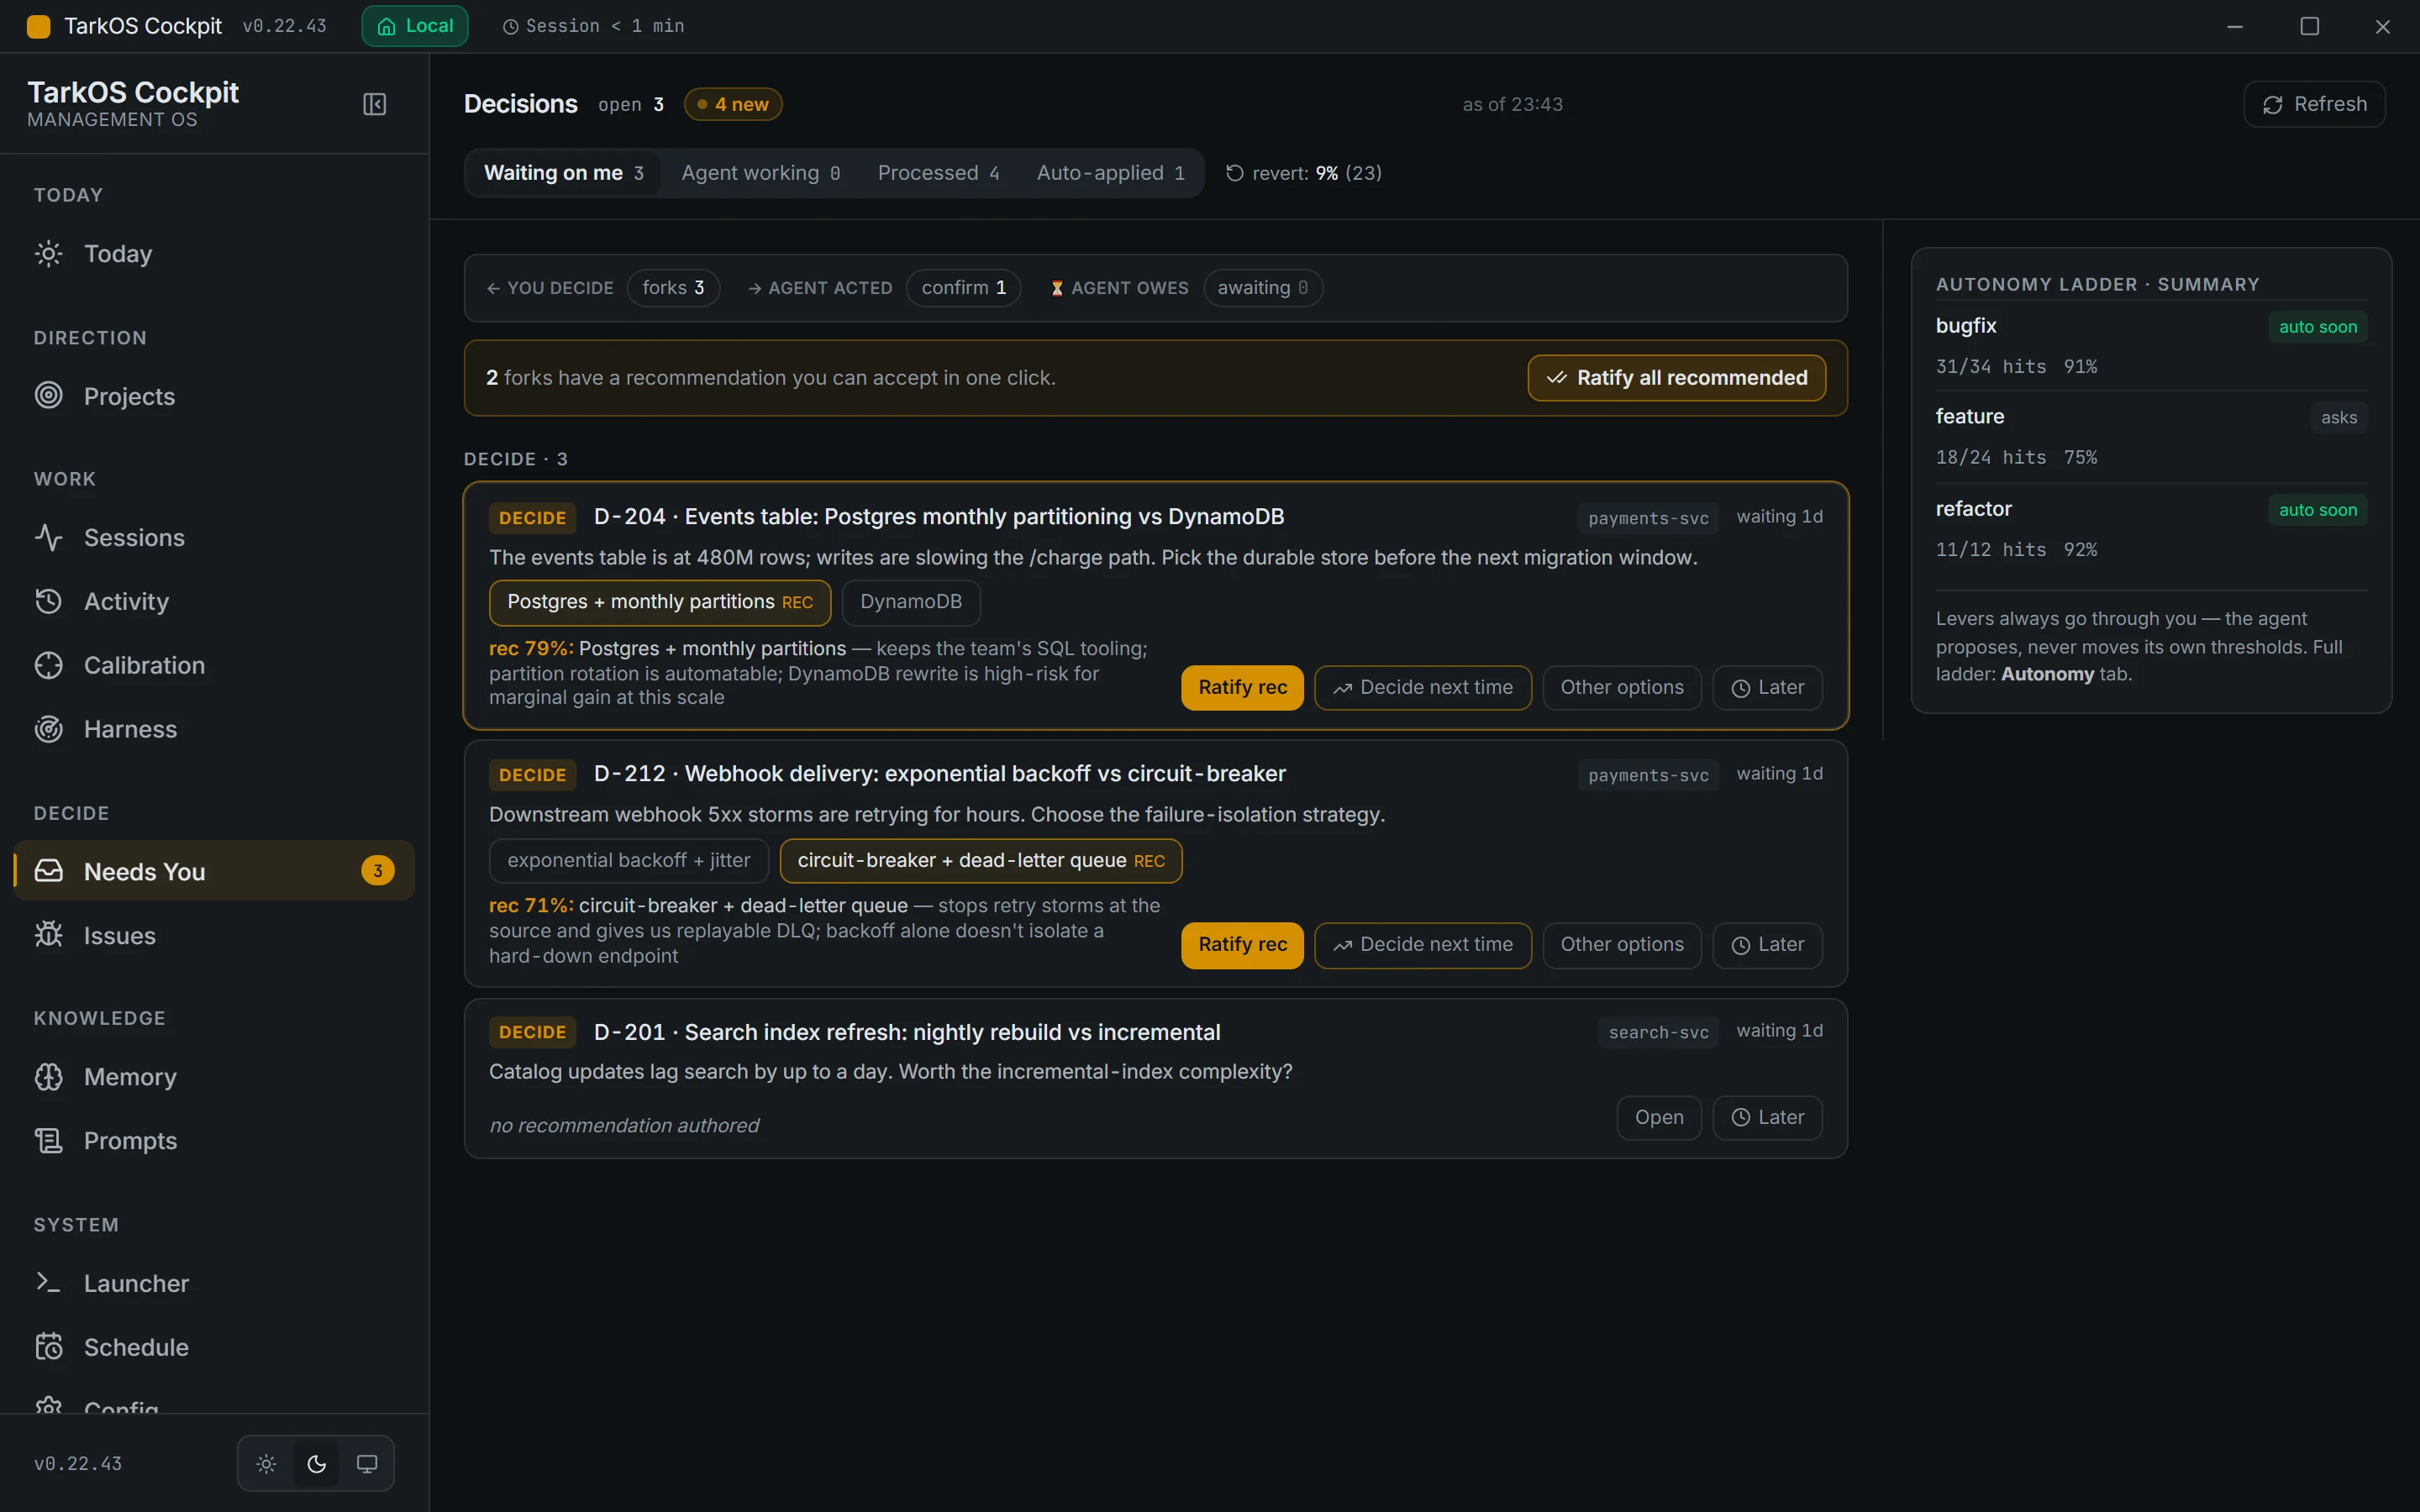
An overnight agent run produces hundreds of changes and a handful of real decisions, and the decisions get buried.

A Tauri app over the harness's files. Reversible actions arrive as receipts; real decisions wait as cards with the agent's recommendation and stated confidence; a calibration view checks that confidence is honest.

  • Tauri 2
  • Rust
  • git-backed state

Try the live demo (opens in a new tab) synthetic data

23 views · 108 backend commands Details : TarkOS Cockpit
fig.3 · cockpit · decisions real capture · synthetic data
FIG. 3 · Decisions that wait for me, with the agent's recommendation and its stated confidence. Synthetic demo data.
Learning build In progress

Agentic Risk Desk

A transaction-analyst agent, my LangGraph learning build, in progress.

Personal learning build · synthetic data

Problem

An analyst agent has to cite the rules it applied, and it must not decide high-risk cases on its own.

Stage 1 is a rules service with sliding windows and categorical escalation, tested on synthetic data. Next: a LangGraph analyst that pauses for human approval on high-risk cases, then an API with tracing and cost per case, then a deploy to AWS Bedrock AgentCore.

  • Python
  • Rules service ✓
  • Planned: LangGraph · FastAPI · AgentCore
stage 1 of 4 · 5/5 planted patterns caught · 59 tests Details : Agentic Risk Desk
fig.4 · risk-desk · plan stage 1 of 4
FIG. 4 · Green = done · dashed = planned. Stage 2 adds the LangGraph analyst and the human approval step.
Observability Paused

Session Analytics

What the agent actually did in a session: tokens, subagents, context pressure.

Paused since September 2026 · written by AI agents under my specification, test contracts and review · private

Problem

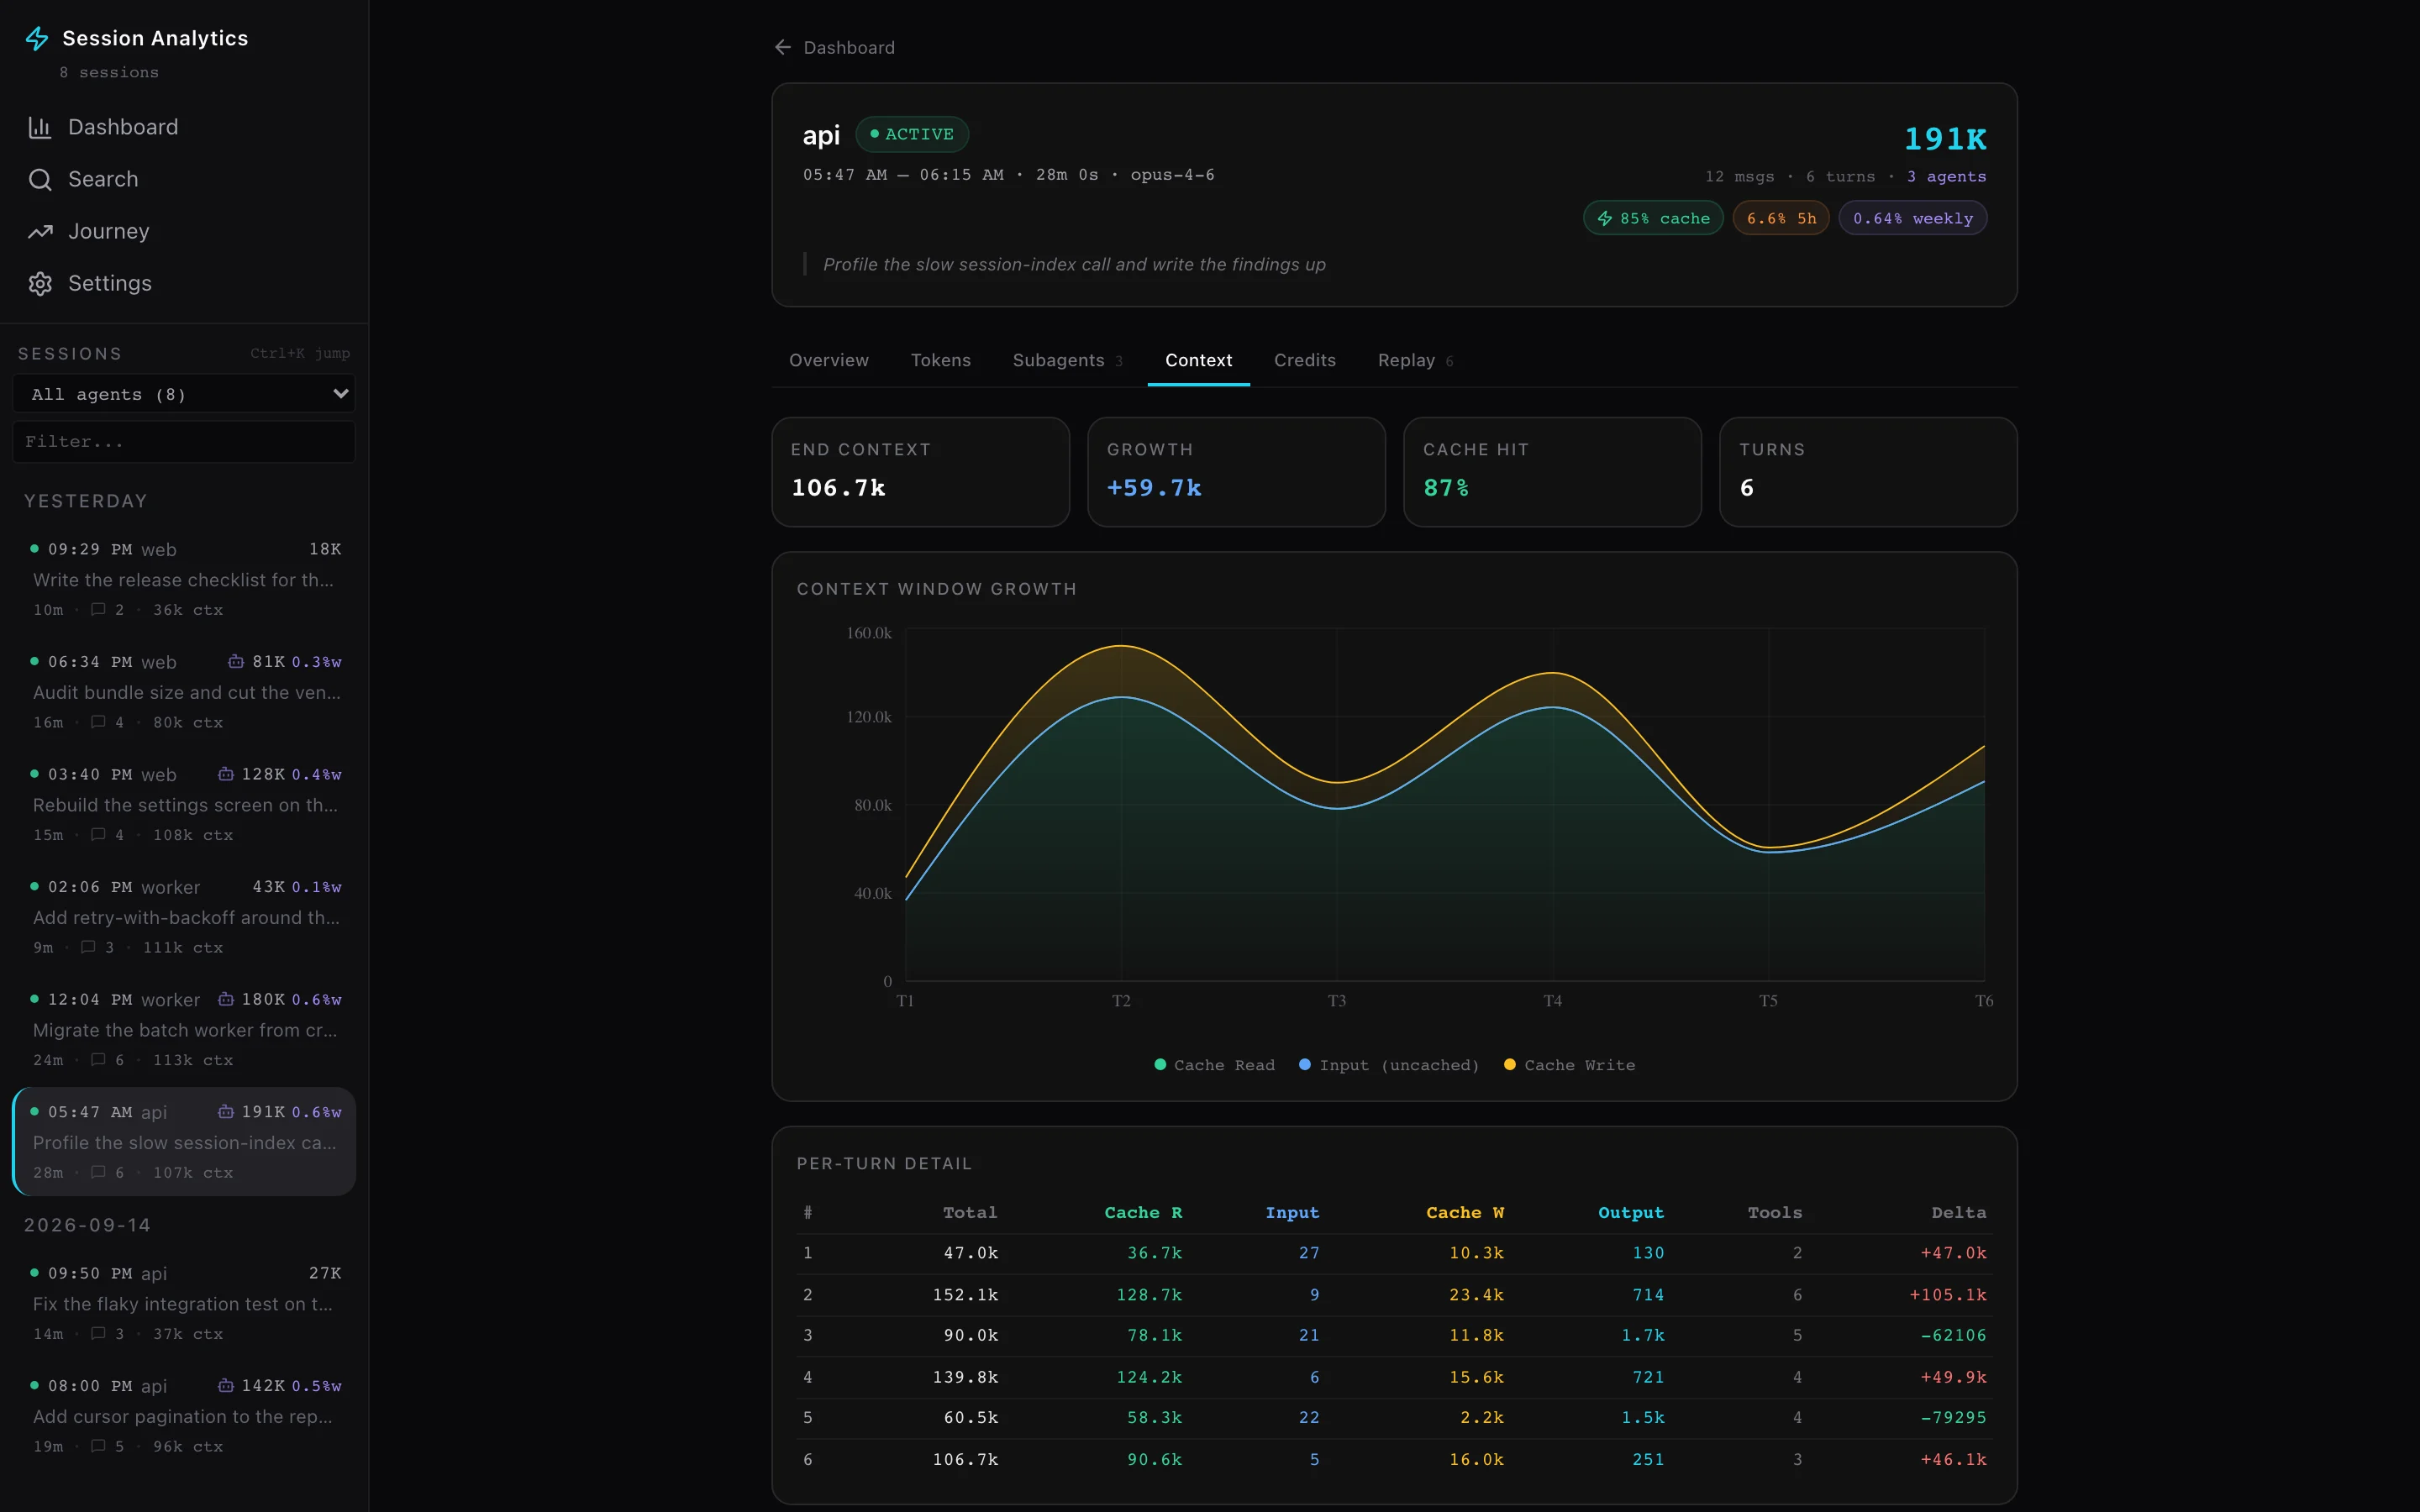
Claude Code's session logs run to gigabytes of JSONL, so nobody reads them, and the reason a run was slow or expensive stays invisible.

A Tauri app over Claude Code's JSONL logs, with a turn-by-turn replay. A rebuild made the session list usable on gigabytes of logs. Set aside since September while I focus on TarkOS.

  • Tauri 2
  • Rust
  • Recharts
1,800+ sessions analyzed · session list 46× faster Details : Session Analytics
fig.5 · session analytics · context real capture · synthetic fixture
FIG. 5 · The context tab of one session, on an invented fixture.
SYS/02 · Capabilities

What I do

CAP-01Harness

Agent harnesses

Instructions, hooks, a decision tray and verification gates that let a Claude Code agent work through a backlog on its own, and stop for me on the calls that matter.

Claude Code · hooks · skills · git-backed state · human-in-the-loop

CAP-02Measure

Evals & measurement

Blind A/B tests of instructions, a cheaper batched eval judge, and instruments that get checked too. I test whether a rule helps before I trust it.

blind A/B · LLM judge · session logs · regression gates

CAP-03Tools

Desktop tools for agent work

Tauri apps I specify, test-gate and use: a launcher for parallel sessions and an operations console. The code is written by AI agents under my specification, test contracts and review of the result. That's the point: shipping them this way is how I know the harness works.

Tauri desktop apps (agent-written) · test contracts · perf harnesses

CAP-04Games

Game engineering

11+ years of C# and Unity: gameplay systems, live ops and multiplayer, including a solo two-region AWS backend (2019 to 2022).

C# · Unity · ECS · live ops · AWS (2019 to 2022)

SYS/03 · Origin

Game systems and agent systems

The through-line isn't a technology, it's a habit: build the system that runs the thing, instrument it, and let the measurements argue. In games that meant 11+ years of gameplay systems, live ops and servers that had to run unattended. Today it means agents that work while I'm away, and the same shapes show up.

DWG G-12 · npc_guard.btUnity · 2015 →
? Selector → Sequence Patrol See player? Chase DECISION CONDITIONACTION
A game NPC's shape: decide, check, act. Every frame.
DWG A-03 · agent_loopAgents · now
? Plan · route Tool call Verify? Done fail → replan DECISION ACTIONCONDITION
An agent's shape: decide, act, verify, loop. Every step.
  • Decision selector · planner
  • Condition see player? · verify?
  • Action chase · tool call
SYS/04 · Games

11+ years of shipping mobile games

Years
11+ yrsC# · Unity
Released titles
6released titles
Crazy Kick downloads
100M+Crazy Kick, lifetime

Crazy Kick's downloads are lifetime and come from the publisher's user acquisition; I've been its sole engineer since mid-2024.

C# · Unity · iOS & Android All games
SYS/05 · Log

Experience & how I work

  1. Q4 2025 → now · Independent, after hours

    Agent tooling, side project

    TarkOS, TarkOS Cockpit and a desktop launcher for Claude Code, all in daily use. Agentic Risk Desk, a LangGraph learning build, is in progress.

  2. 12.2017 → now · Orbital Knight, Warsaw

    Senior Unity 3D Developer

    Sole engineer on Crazy Kick since 07.2024: live ops, A/B tests, ads, IAP and analytics. Earlier: a solo two-region AWS multiplayer backend (2019 to 2022), work on two EU Horizon 2020 research projects, and shipped F2P titles.

  3. 02.2015 → 12.2017 · Fuero Games, Warsaw

    Unity 3D Developer

    Gameplay and client systems for Winions: Mana Champions and Age of Cavemen, including client-side multiplayer integration.

  4. 2015 → 2019 · WSB University, Warsaw

    BSc Computer Science

How I work with agents

  • RULE 01

    I architect and gate; the agent implements. I write the spec and the test contract, the agent writes the code, and I review the result.

  • RULE 02

    Verdicts come from output. A task is done when a test, a diff or a screenshot says so, not when the agent says so.

  • RULE 03

    Volume is not progress. One night an agent produced roughly 300 commits and closed 21 tasks. I graded it a failure: almost nothing I needed had been done.

  • RULE 04

    Measure, then change. Instructions earn their place in a blind A/B, and the tools get measured before they get rewritten.

SYS/06 · Contact

Contact

Running agents past the context limit, or just curious how the harness works? I read everything sent here.

NowAgentic Risk Desk stage 1 of 4 · preparing the launcher for release

Przemysław Tarkowski
Przemysław TarkowskiSoftware engineer · AI agent tooling